This post is the written version of my five-minute Pecha Kucha pitch (15 slides, 20 seconds each) for my MaCAD thesis at IAAC. The idea is simple to say and hard to do: decompose BIM models into meaningful parts, and use them to generate new, valid models. Here is the story in seven parts: what is already done, and what is still only a plan.
1. The need: BIM data that is not ready for AI
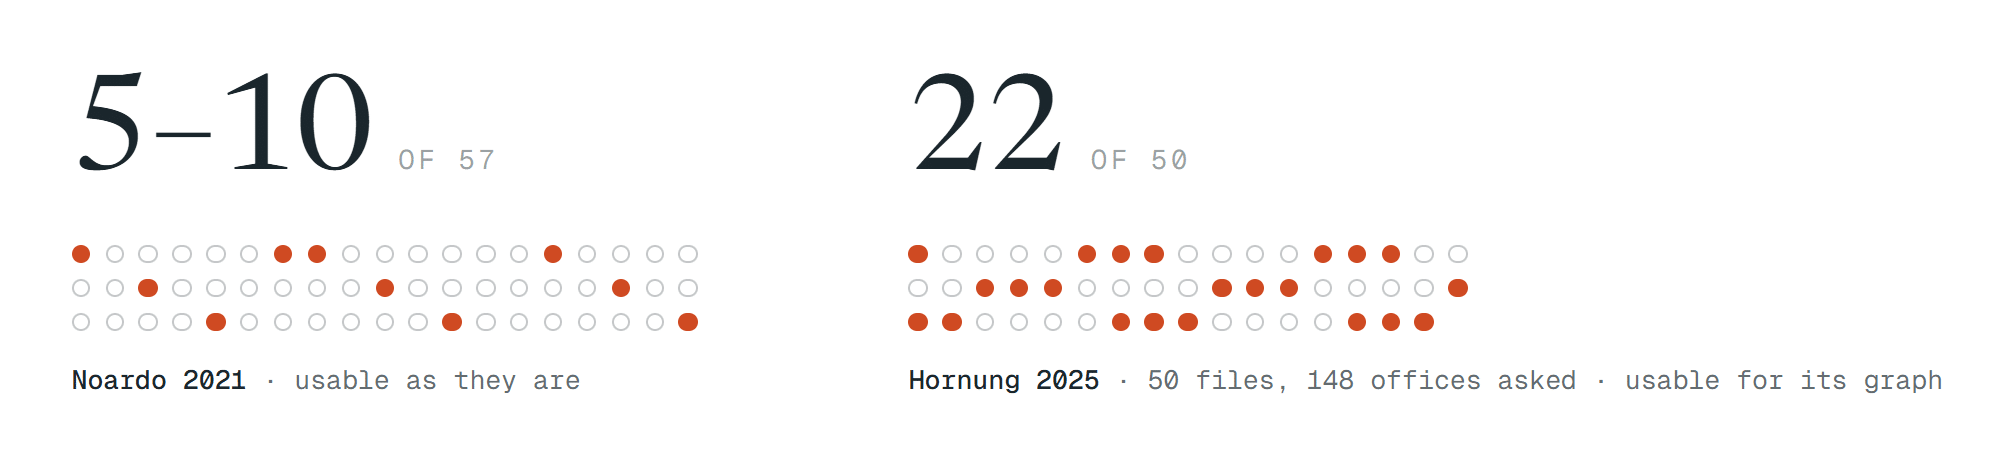
Most real BIM models are not ready to teach an AI. In a study of 57 IFC models from practice, only five to ten were usable as they were. Another team asked 148 offices and got 22 usable files, partly because of its six-class filter. These are samples from research partners and one region: a pattern, not a census.
2. The paradox: the data exists, but it does not carry over
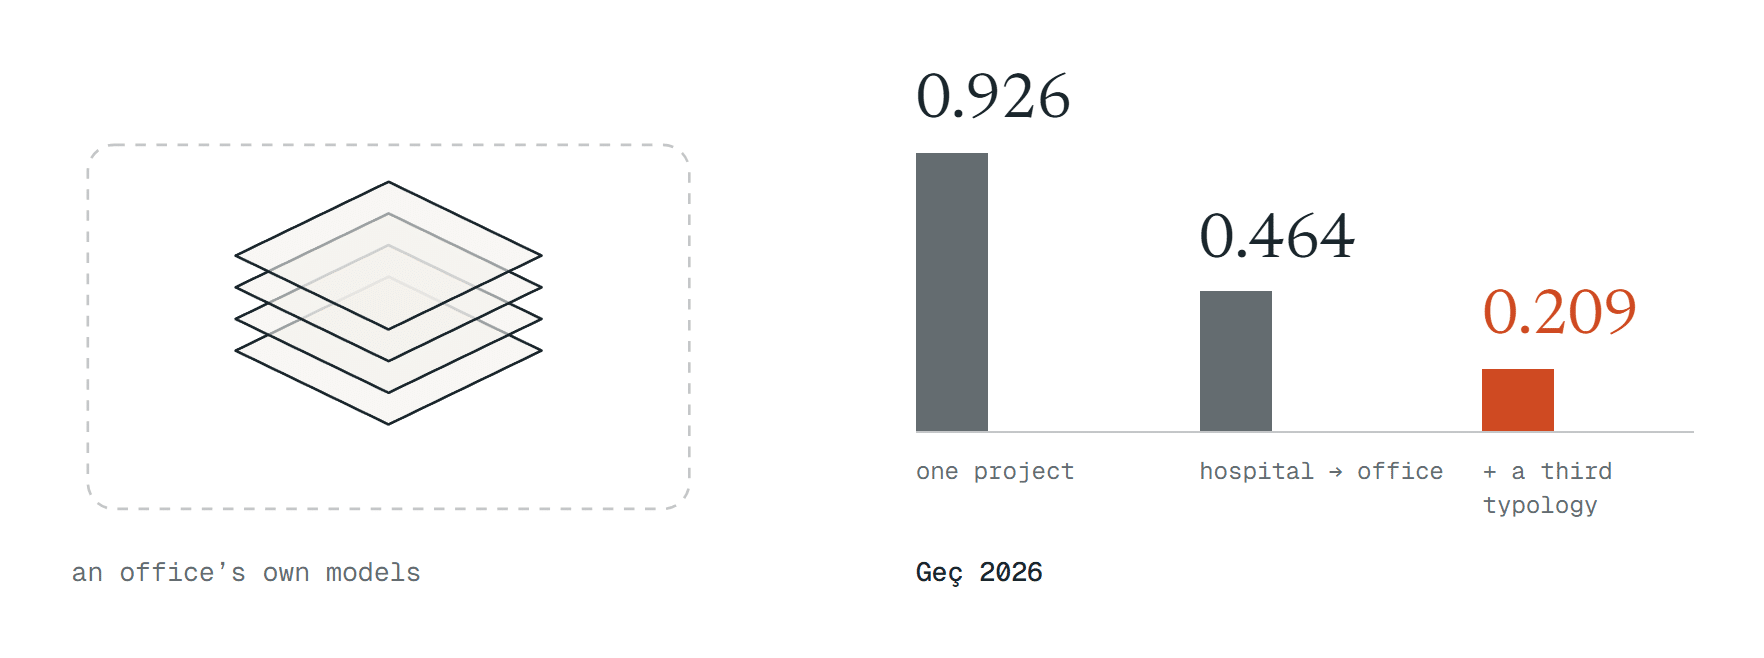
Every office holds years of models, but they sit inside each office. And what one project teaches does not carry over. In one study, door-specification accuracy (macro-F1) drops from 0.926 for one project to 0.464 across a hospital and an office, and to 0.209 when a third typology is added. In another, accuracy falls from over 99% to 81–90% on a file the model never saw.
3. The research question
So the question behind the thesis is:
can we decompose BIM models into meaningful parts and use them to generate new, valid models?
My hypothesis is that if a model is broken into its elements and relations, an AI can find the patterns it needs to build something similar.
4. The method in three steps
Step 1 · Decompose (done, with no AI)
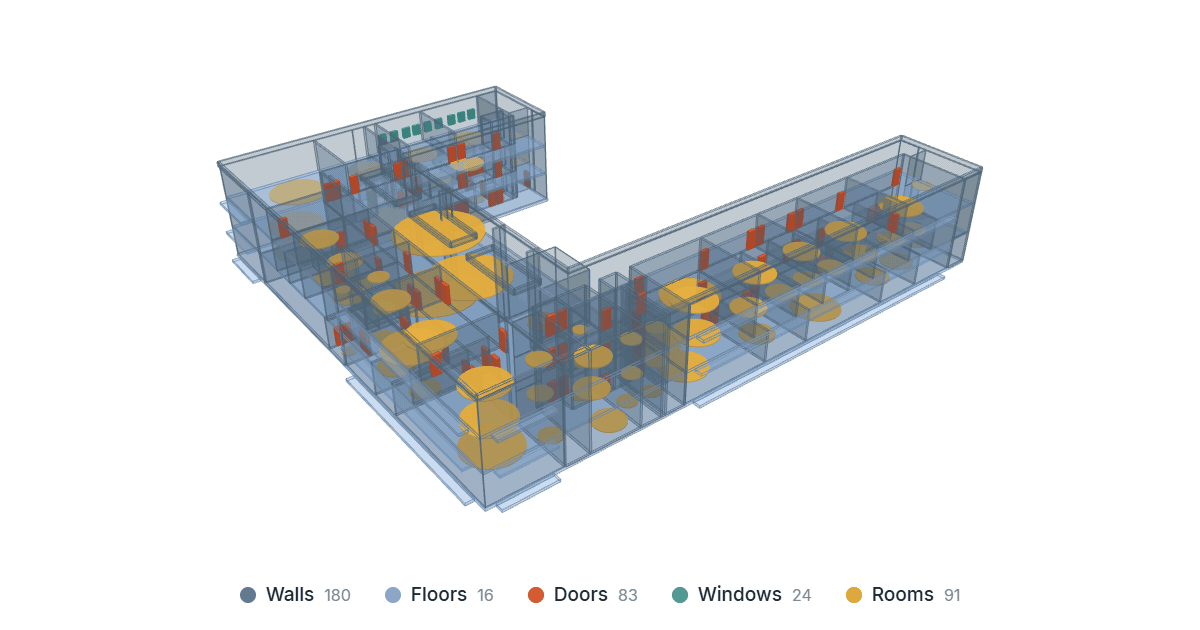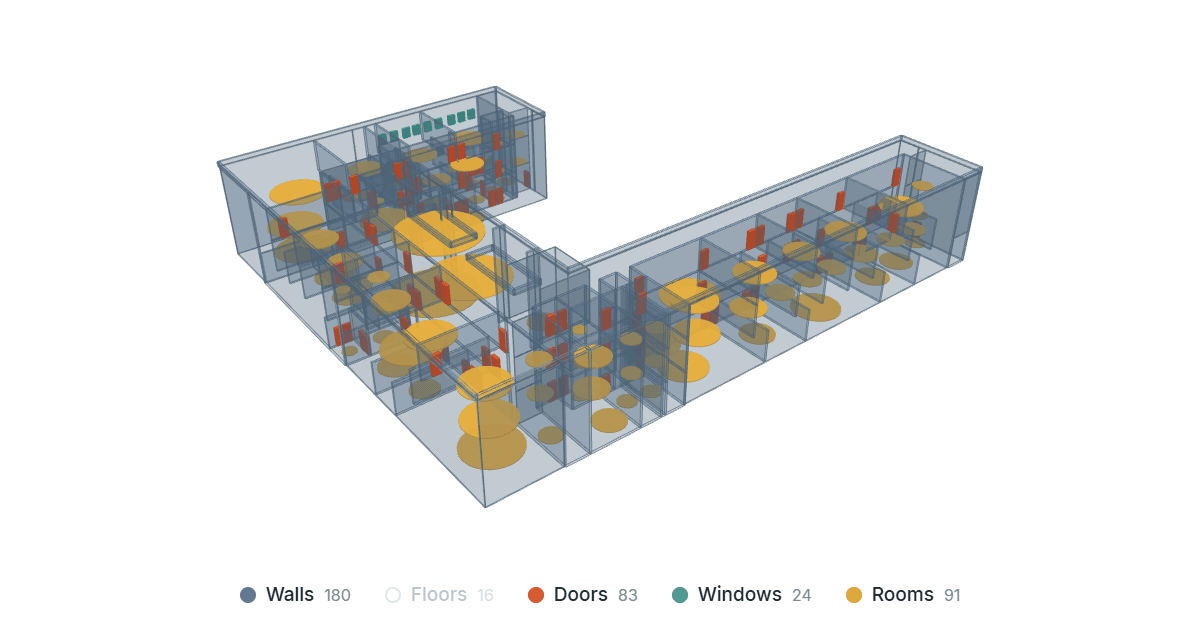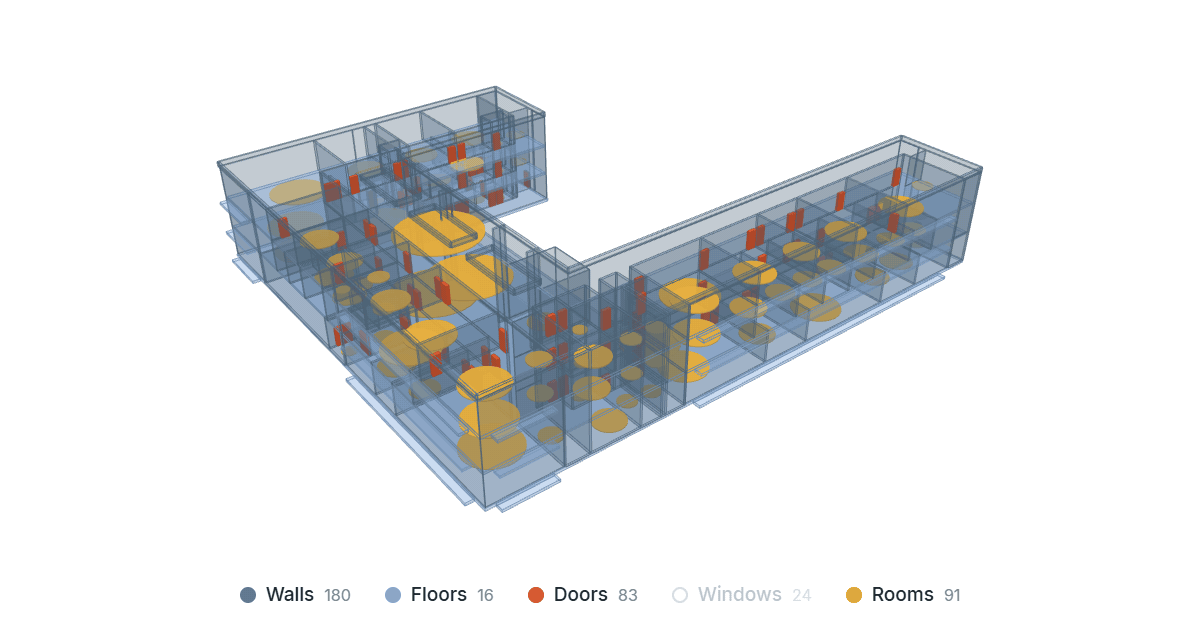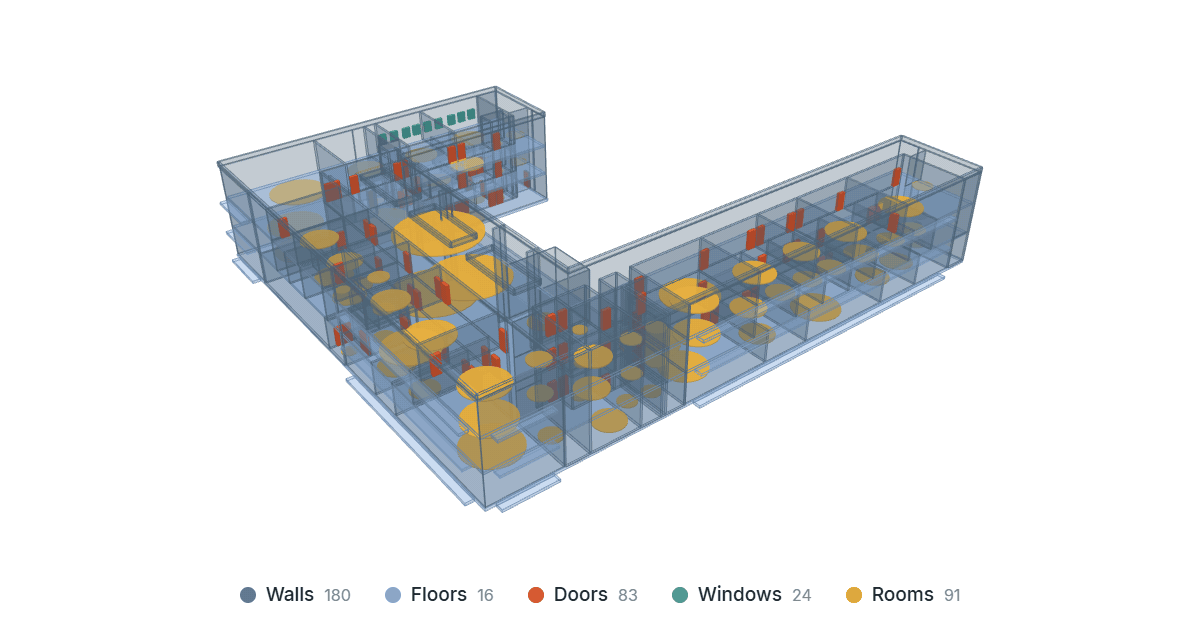
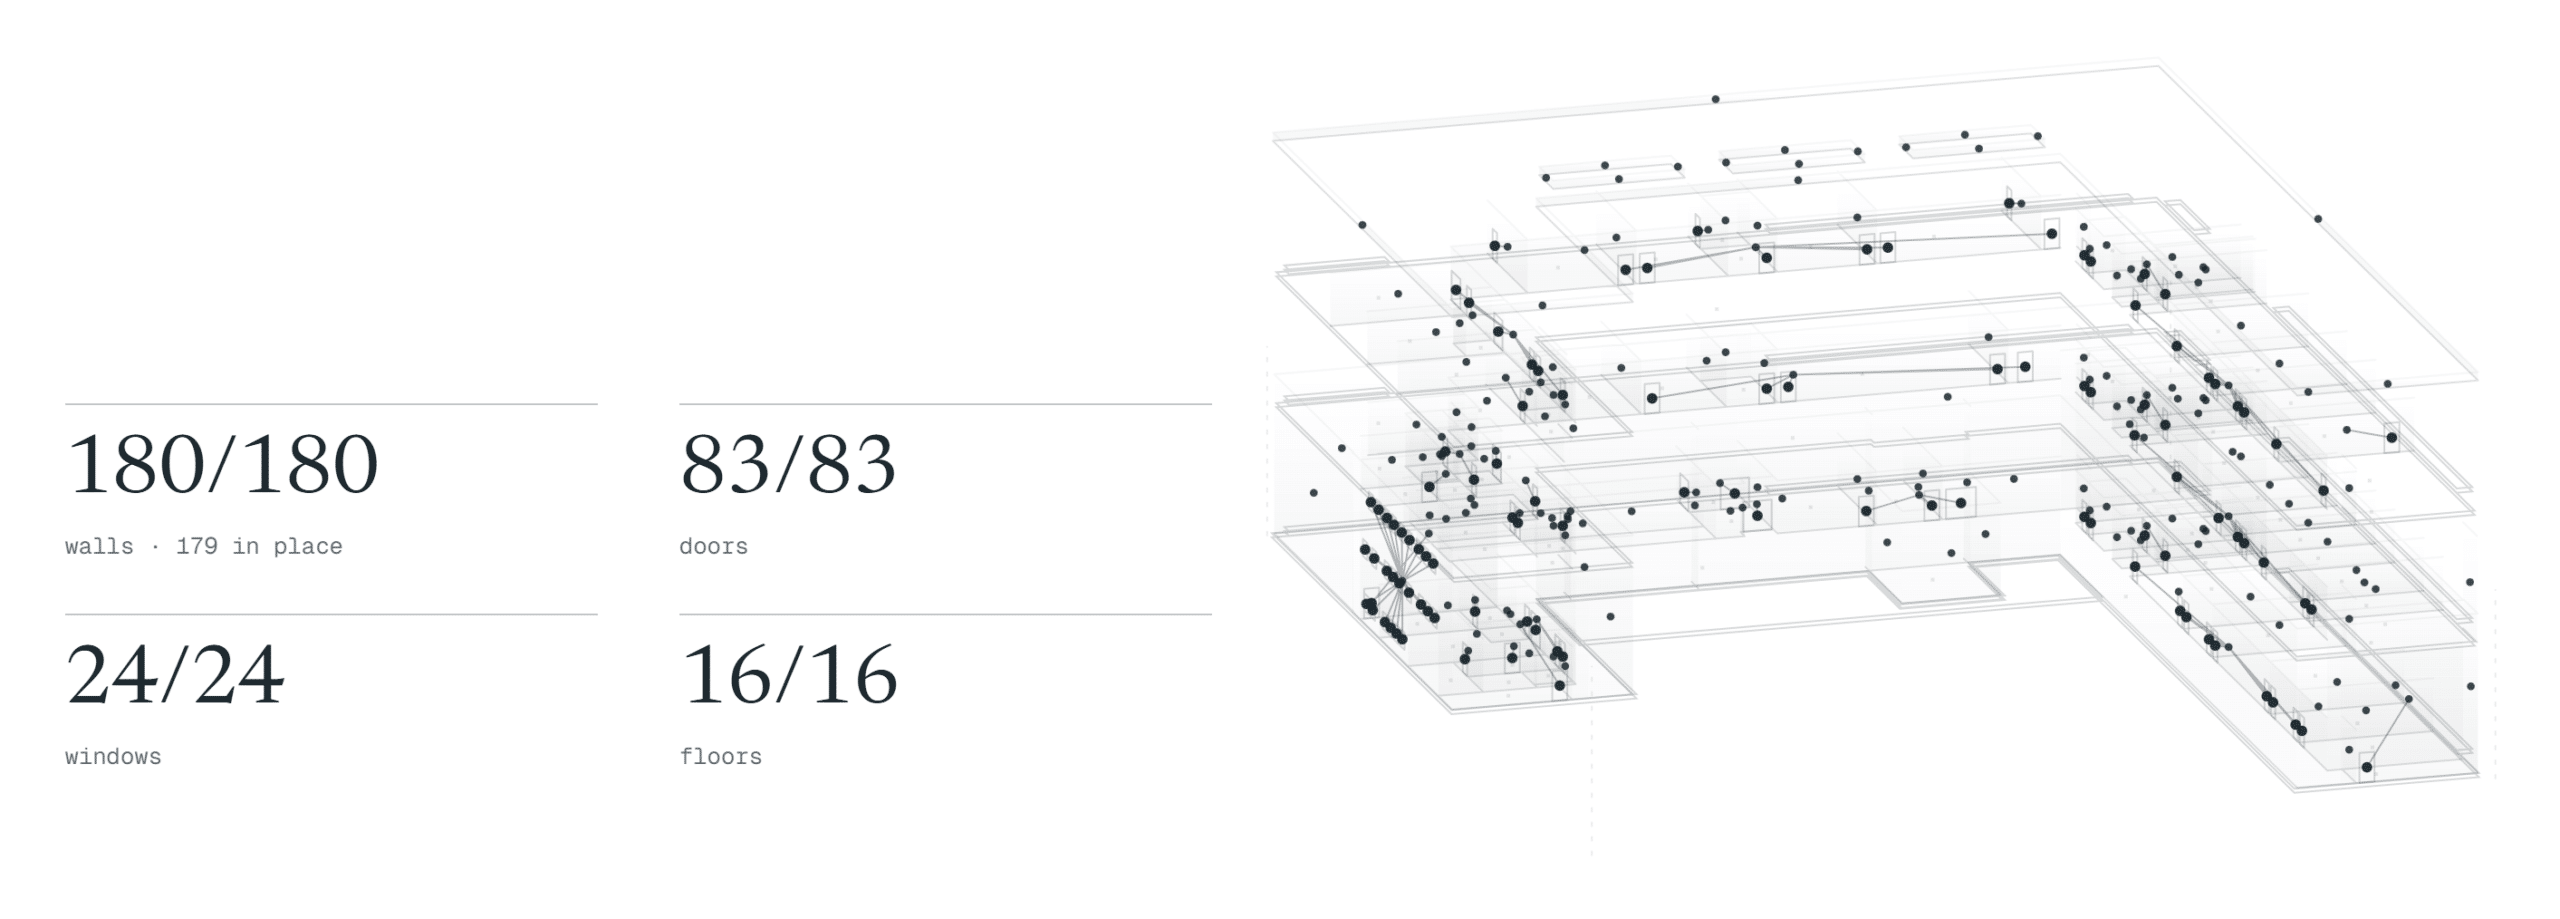
Every element goes out of Revit to text and comes back. On Autodesk’s sample project, the round trip returned 180 of 180 walls (179 in place), 83 of 83 doors, 24 of 24 windows and 16 of 16 floors. Rooms rebuild less well: 86 of 91 stay enclosed. The mechanics work.
Step 2 · Mask (the plan)
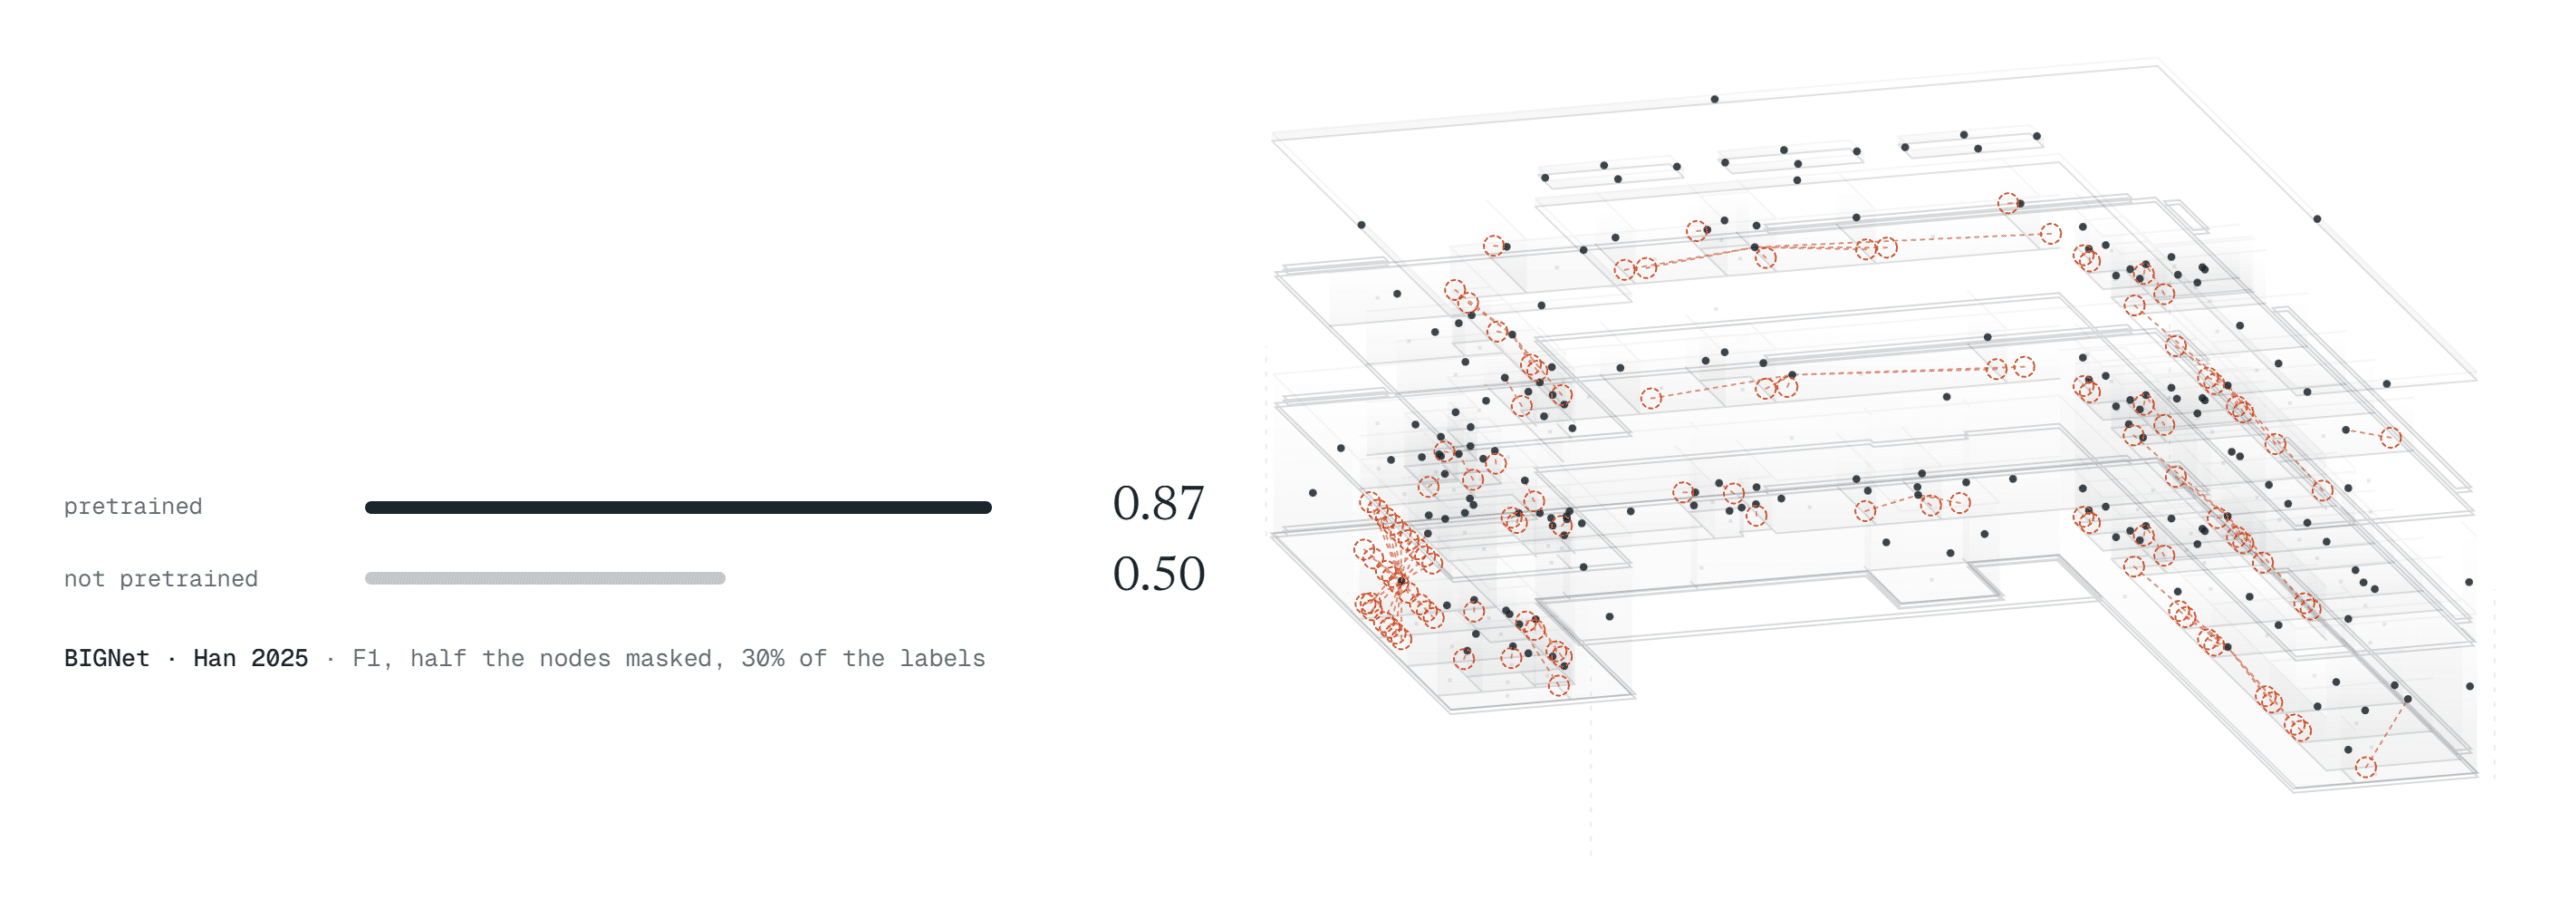
This is the direction my supervisor approved: learn by hiding. I hide part of a model and ask the AI to predict it. The literature points the right way. BIGNet masks half of the nodes and, with only 30% of the labels, reaches an F1 of 0.87 against 0.50 without pretraining. It is still a plan, not my result.
Step 3 · Assemble (the plan)
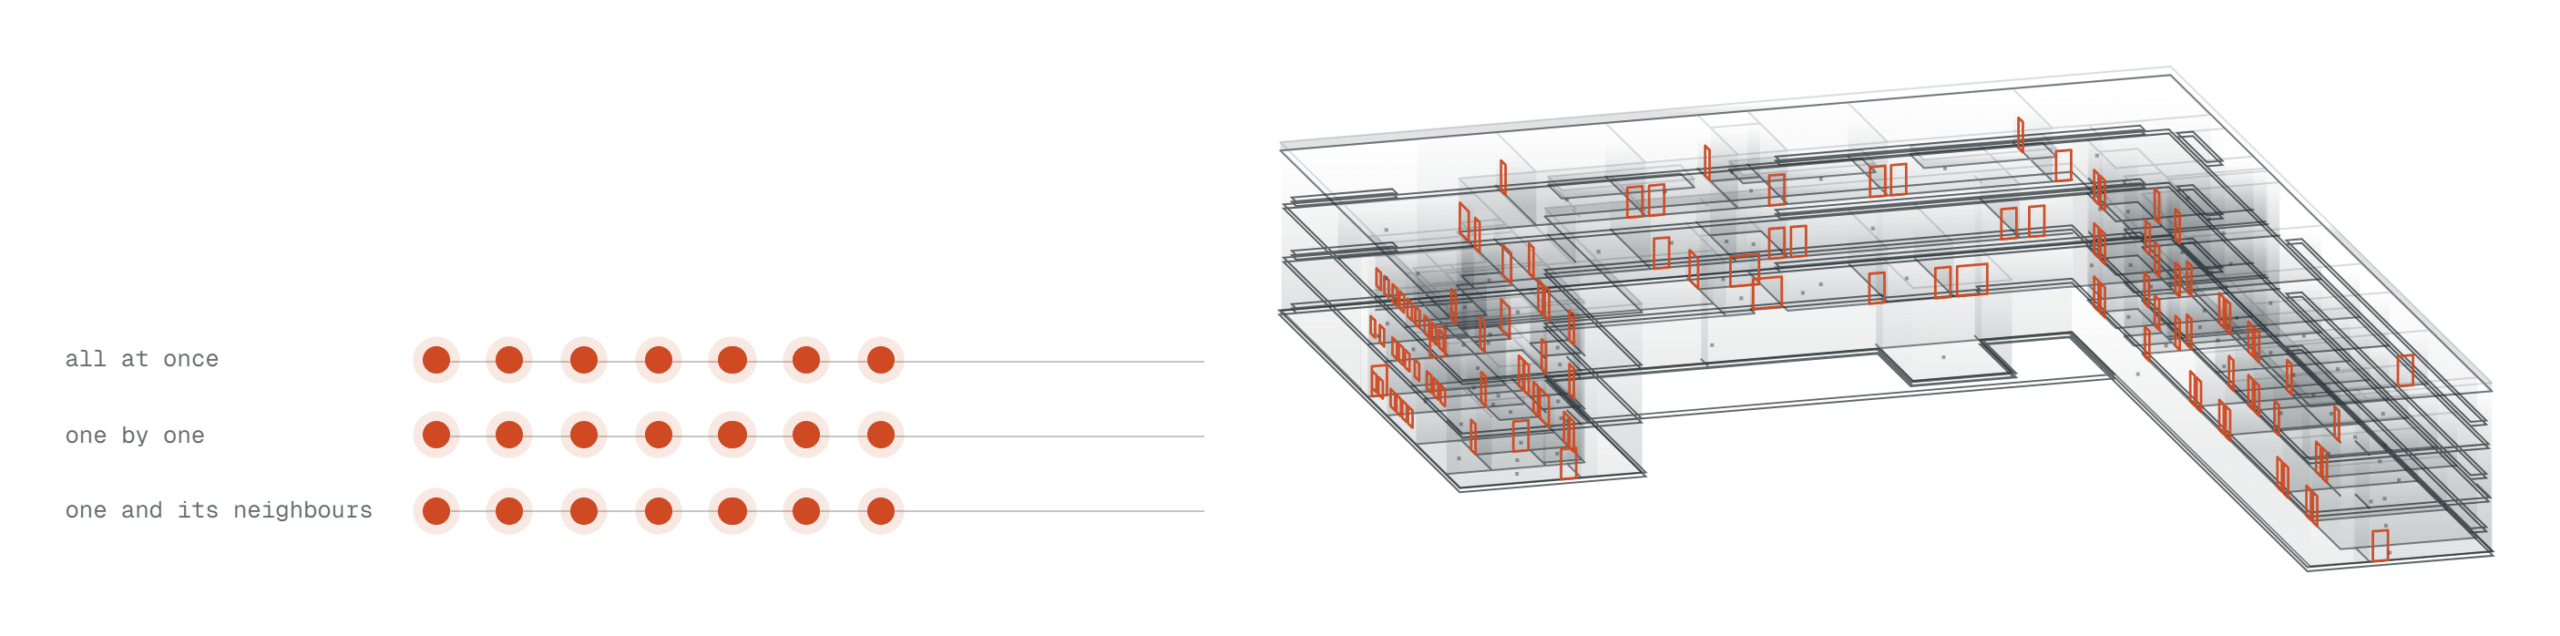
The AI proposes, and an MCP server builds it in Revit. The order of placing is the experiment: all at once, one by one, or one and its neighbours. The key test is new, not a copy: learn from nine models, test on one the model has never seen. Again, this is a plan.
5. Who it is for, and how it works
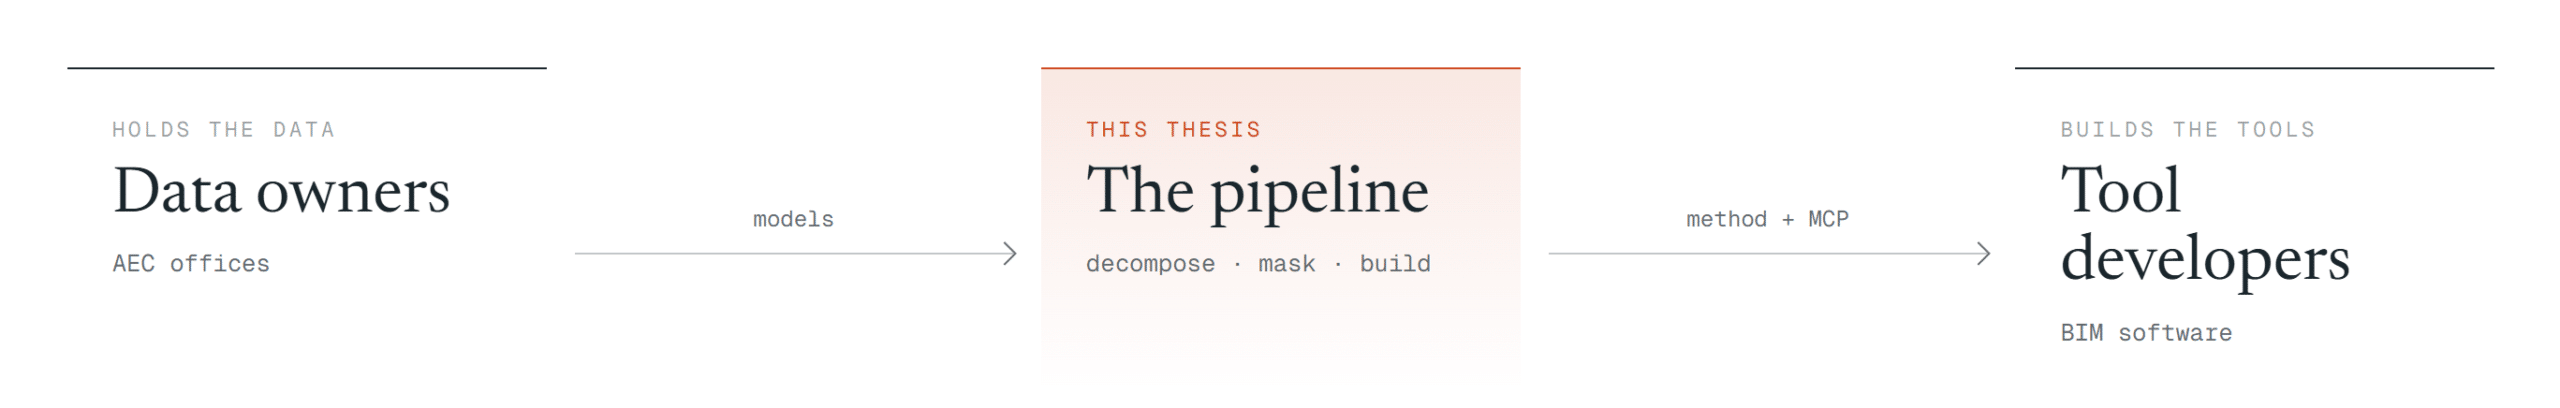
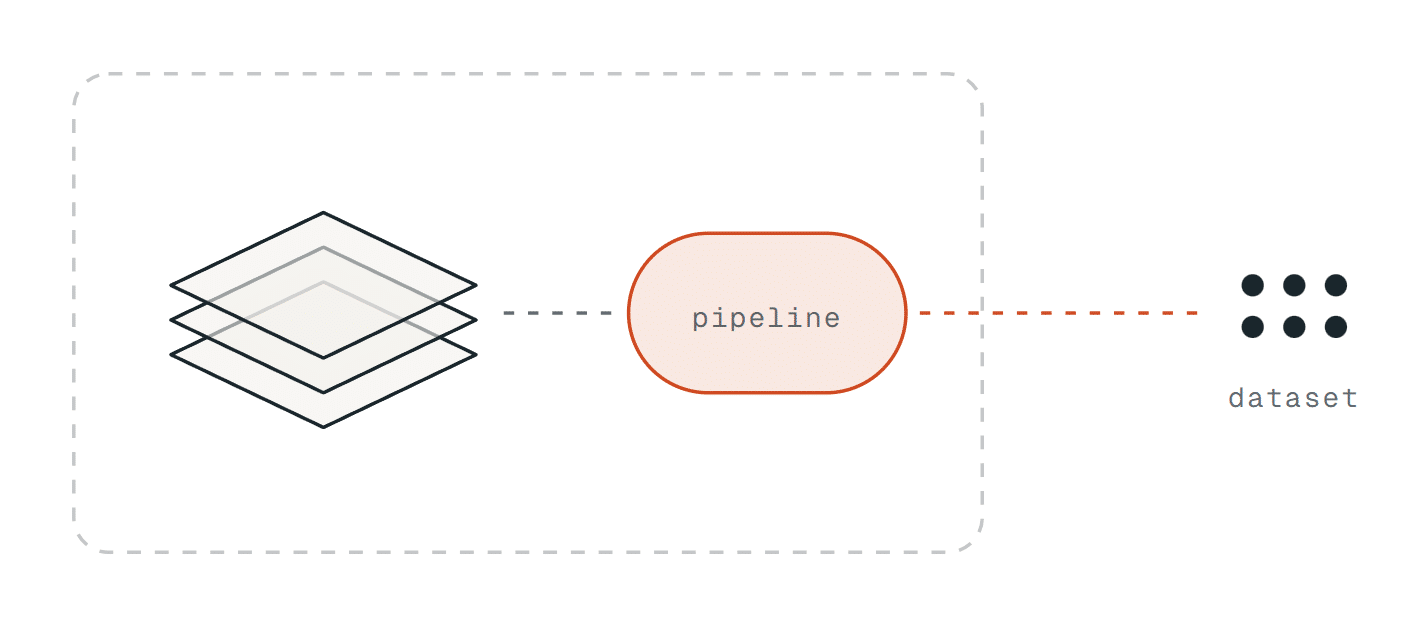
Two actors matter. Data owners are the AEC offices that hold the models. Tool developers build what offices use. In the middle sits the pipeline: models go in, and a method and an MCP server come out.
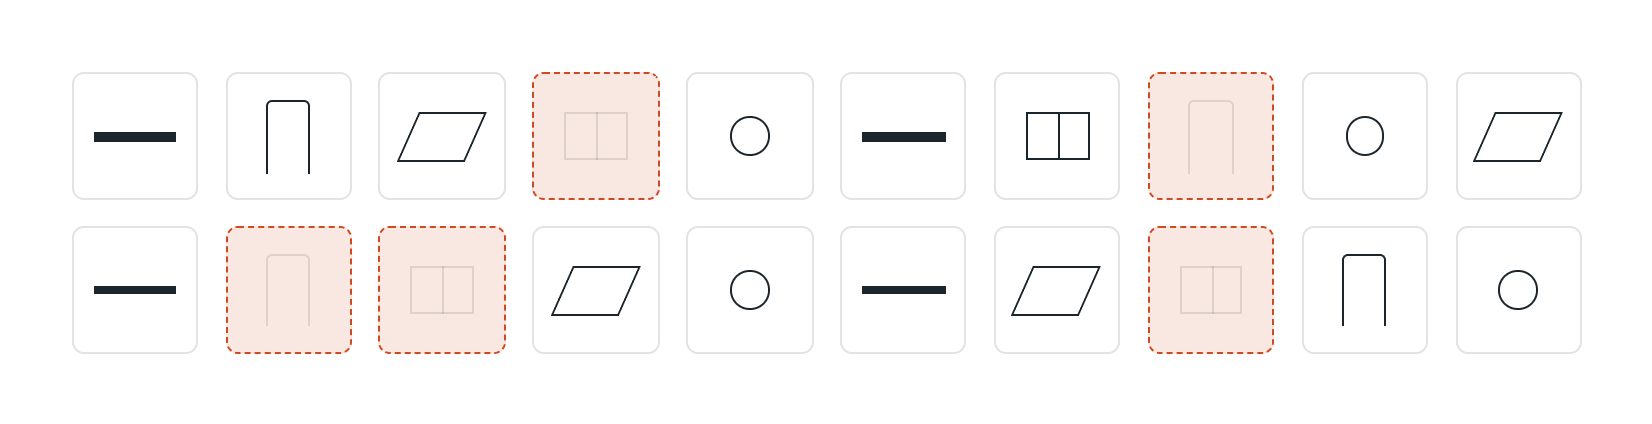
What I exploit is the parts: walls, doors, windows, floors and rooms, with their relations. Together they become a dataset of examples, and some are masked so the AI learns to fill them back in. The raw material is not the file but what is inside it.
The pipeline runs inside the office, on its own models. The files stay there; only the derived dataset leaves. An office can learn from its own history without handing over its project files.
Offices come first, and this is an open invitation: give me ten of your Revit models and I will turn them into a decomposed dataset and a first masking test. No office has joined yet; the offer is open.
6. Goals, horizon and impact
By the end of the thesis the goal is a method and a pipeline, with results on ten models of one typology. That is the goal, not something I have today. The long-term horizon is a co-pilot inside Revit, trained on each office’s own data, that proposes the next element while the modeller keeps the criteria and the choice. It is a direction, not a promise.
The impact has two sides. Technological: real models become training data, which is what the literature says is missing. Professional and social: the work moves from drawing to criteria and choice, and the data stays in the office’s hands. I am not claiming savings in hours or money; I do not have that evidence.
7. Where I am, and what I need
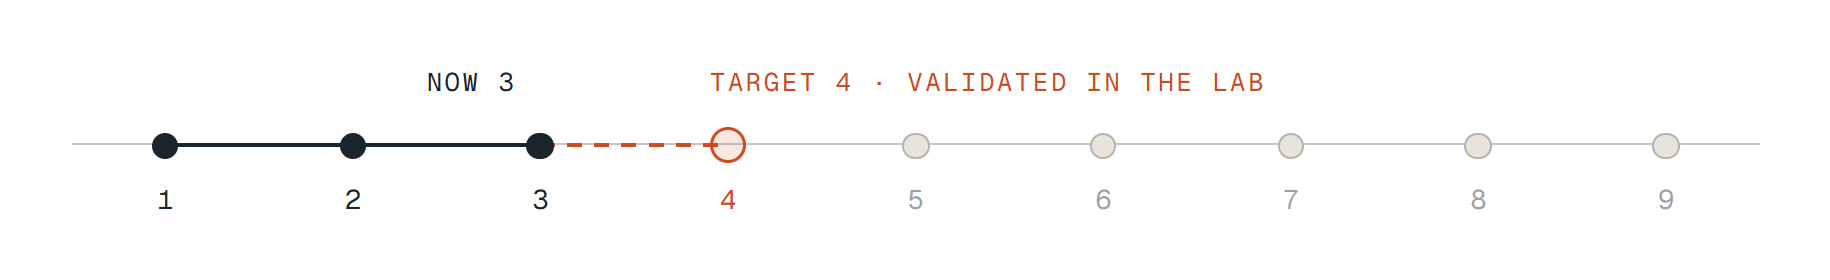
Today the thesis is at technology readiness level 3: the round trip works in the lab, on one sample model. The aim is level 4, validated in the lab, through four steps: gather ten models and mask them, MCP assembling in Revit, the three placement orders, and the new-versus-copied test.
I would love your feedback on two questions:
- What should be hidden first? An element, a relation, or a whole class such as the openings?
- How do we prove that what the AI generates is new, and not a copy?
References
- Noardo et al., 2021. An Inspection of IFC Models from Practice.
- Hornung et al., 2025. Augmenting IFC-Based BIM Models for Graph Neural Network Training.
- Geç & Güzelci, 2026. ML-based decision support for BIM component specification.
- Austern et al., 2024. Incorporating Context into BIM-Derived Data.
- Han et al., 2025. Pretrained graph neural network for embedding semantic, spatial, and topological data in building information models.
- MCP4IFC, 2025. IFC-Based Building Design Using Large Language Models.
G. Ramón García Ayala · MaCAD, IAAC.